| 일 | 월 | 화 | 수 | 목 | 금 | 토 |
|---|---|---|---|---|---|---|
| 1 | 2 | 3 | ||||
| 4 | 5 | 6 | 7 | 8 | 9 | 10 |
| 11 | 12 | 13 | 14 | 15 | 16 | 17 |
| 18 | 19 | 20 | 21 | 22 | 23 | 24 |
| 25 | 26 | 27 | 28 | 29 | 30 | 31 |
Tags
- 구현
- python
- dp
- 아니메컵
- ps
- 부분수열의 합2
- lgb
- 파이썬
- 코딩테스트
- 코복장
- 백준
- 스펨메일 분류
- BFS
- 샤논 엔트로피
- 다이나믹 프로그래밍
- populating next right pointers in each node
- 정렬
- 17070
- 실질적 약수
- dfs
- 코딩
- 27448
- 2247
- 딥러닝
- C
- 코테
- 정답코드
- 모두의 꿈
- T tree
- 힙 정렬
Archives
- Today
- Total
코딩복습장
[CS231n] SVM 과제 본문
728x90
 for i in range(num_train):
        scores = X[i].dot(W)
        correct_class_score = scores[y[i]] #eqivalent to s_yi in slides
        for j in range(num_classes):
          margin = scores[j] - correct_class_score + 1
          if j == y[i]: # if the correct class== the class we are paying attention
            continue
          if margin>0:
            loss+=margin
            dW[:,y[i]]-=X[i]
            dW[:,j]+=X[i]


    # Right now the loss is a sum over all training examples, but we want it
    # to be an average instead so we divide by num_train.
    loss /= num_train

    # Add regularization to the loss.
    loss += reg * np.sum(W * W) # L2 loss

    #############################################################################
    # TODO:                                                                     #
    # Compute the gradient of the loss function and store it dW.                #
    # Rather than first computing the loss and then computing the derivative,   #
    # it may be simpler to compute the derivative at the same time that the     #
    # loss is being computed. As a result you may need to modify some of the    #
    # code above to compute the gradient.                                       #
    #############################################################################
    # *****START OF YOUR CODE (DO NOT DELETE/MODIFY THIS LINE)*****
    dW/=num_train
    dW+=2*reg*W
함수의 모든 부분을 가져온 것은 아니다. 여기서 내가 어려웠던 것은 margin>0인 경우에 를 계산하는 부분이다. 일단 svm function을 내가 미분해서, 코드에 맞게 변형해야 한다.
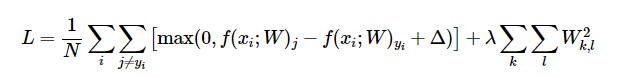
이 식을 잘 생각해야한다.
loss function에서 와 가 같은 경우는 제외하고 계산하기 때문에, 에 대해 미분한 것과 에 대해 미분한 것을 구별해줘야 한다. 물론 위의 식에 regularization도 미분한 걸 적용해줘야 한다.
correct_y_scores=scores[np.arange(num_train), y].reshape(num_train,1)
    margin=np.maximum(scores-correct_y_scores+1,0)
    margin[np.arange(num_train), y] = 0 # Correct class=0
    loss=np.sum(margin)/num_train
    loss += reg * np.sum(W * W)


    # *****END OF YOUR CODE (DO NOT DELETE/MODIFY THIS LINE)*****

    #############################################################################
    # TODO:                                                                     #
    # Implement a vectorized version of the gradient for the structured SVM     #
    # loss, storing the result in dW.                                           #
    #                                                                           #
    # Hint: Instead of computing the gradient from scratch, it may be easier    #
    # to reuse some of the intermediate values that you used to compute the     #
    # loss.                                                                     #
    #############################################################################
    # *****START OF YOUR CODE (DO NOT DELETE/MODIFY THIS LINE)*****
    dW=(margin>0).astype(int) #111...0111 -> correct class has label 0.
    dW[np.arange(num_train),y]-=dW.sum(axis=1)#dW has shape (3073,10)-> so sum w.r.t class dimension. we subtract (classes-1) -> 1 being correct class.
    dW=X.T.dot(dW)/num_train +2*reg*W
여기서 어려웠던 부분은 margin 행렬에서, != 인 자리에서는 margin을 제대로 계산하고 ==인 class들 자리에는 0을 넣는다는 것이다. 이게 말로는 쉬운데, margin 값을 다 계산하고 그 이후에 margin[np.arange(num_train),y]로 접근할 생각을 못했다.
추후에 한번 더 봐야할 것 같다.
728x90
'CS231n' 카테고리의 다른 글
| [CS231n] RNN Captioning 과제 (0) | 2025.06.30 |
|---|---|
| [cs231n] Pytorch과제 (0) | 2025.06.30 |
| [CS231n] ConvolutionalNetwork과제 (0) | 2025.06.29 |
| [CS231n] Dropout 과제 (0) | 2025.06.29 |
| [CS231n] Batch Normalization 과제 (1) | 2025.06.29 |
'CS231n' Related Articles
more


Comments